AI for Court Documents: Catch Fake Citations Before You File
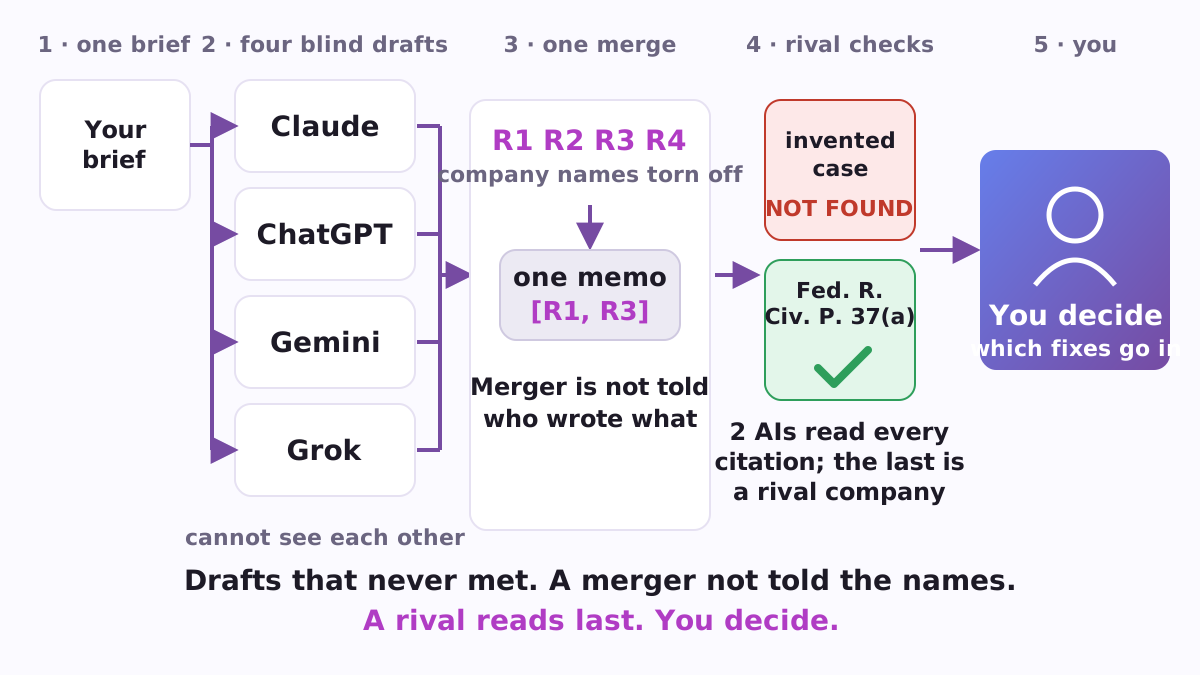
If you are going to court without a lawyer and using ChatGPT, Claude or Gemini to help with the paperwork, the most expensive mistake is not clumsy writing. It is a confident sentence that cites a case that does not exist. Docprep is a free, open-source program that changes how the AIs are arranged rather than which AI you use. Several AIs from different companies each write a complete draft of the same document without seeing one another. One AI merges the drafts without being told which company wrote which. Two AIs then check the merged text, citations first, and the last of them comes from a different company than the one that merged it. You get the document, both checking reports and a record of the run, and you decide which fixes go in.
It runs on your own computer. With API keys (the passwords that let a program talk to an AI company's models directly) it runs by itself. Without them, it hands you each step as a file to paste into the AI chat sites you already use, and picks up where you left off. It works for any document whose claims need sources, such as a report, an insurance appeal or a complaint to a regulator, and its example task is a motion a self-represented litigant might need.
Why one AI is not enough for a court filing
Made-up citations are not rare accidents. On 10 October 2026 the AI Hallucination Cases database kept by the researcher Damien Charlotin listed 2,184 court decisions dealing with AI-made content such as fake citations; in 1,259 of them the party was a person representing themselves. In August 2026 a California appeals court ordered a husband and wife who had appealed without a lawyer to pay the other side's attorney fees on appeal, because they had relied on non-existent authorities and fabricated quotes (California Courts Newsroom). The federal court for the Middle District of Georgia tells self-represented parties plainly that "AI does not alleviate a party's responsibility for making sure that all facts and legal authorities cited in court filings are accurate" (M.D. Ga.).
More people face that job: the share of U.S. federal civil cases filed without a lawyer rose from a long-run average of 11% to 16.8% in fiscal 2025 (Shah and Levy, via beSpacific). Newer models do not fix it alone. Princeton researchers checked over 8,000 citations from eight generations of free ChatGPT models and found GPT-5.1 hallucinating at 6.57%, "a statistically significant regression". The same study points to the remedy Docprep is built around: an AI checker allowed to search legal databases and the open web caught every non-existent citation in the test (Princeton CITP).
How it works
Docprep takes one written task through five steps, and each step is defined by what the AI in it is allowed to see.
- One brief. You write the task once: what you need, the jurisdiction, the format, what counts as a source. The example asks for a memorandum on whether a self-represented litigant in federal court may move to compel discovery responses answered only with boilerplate objections.
- Separate drafts. At least three AIs from at least three companies each write a full draft, with web search on where available. None sees another's draft. Each must cite a source for every statement, mark what it could not verify as "unverified", and not "hedge toward a middle position", so disagreements show.
- A blind merge. One AI receives the drafts as R1, R2, R3 in random order; a draft that names its maker has that phrase replaced with "[vendor name removed]". The merger tags each claim with the drafts behind it, as in [R1, R3], and writes a log of what the drafts agreed on, where they disagreed and how each conflict was settled. A merge without that log stops the run.
- A check from inside. An AI from the merger's own company reads the result in a fresh session, checks that every source exists and says what is claimed, ranks findings Critical, Major and Minor, and gives a verdict.
- A check from outside. An AI from a different company reads the document and the first report, confirms or disputes each finding, adds its own and gives the closing verdict.
Everything lands in one folder: the brief, every prompt and draft, the merged document, the merge log, both reports and a manifest.json record. No critic's fix is applied to your text automatically; you choose. Pinpoint page numbers deserve your closest look, since that is where even searching AI checkers are weakest (the Princeton agent caught only 18.2% of wrong pincites), and opening the case at the cited page settles it.
Why these rules
- The drafts never meet. In AI debates, models often switch from a correct answer to a wrong one when a peer argues persuasively (Wynn, Satija and Hadfield, 2025).
- The merger is not told who wrote what. AI judges tend to score their own output higher, and can recognise it (Panickssery, Bowman and Feng, 2024). The key to the labels goes only into the record, so you can later count how often a merger favoured its own company.
- The last reader comes from another company. In a study of more than 350 models, when two were both wrong they gave the same wrong answer about 60% of the time on one leaderboard (Kim et al., ICML 2025). A critic trained elsewhere is the most direct route to shared blind spots.
- Every critic must be able to search. Docprep refuses to start if a critic has no search tool.
- The rules are code.
python3 docprep.py checkrefuses a setup that breaks them, for example one where the closing critic comes from the merger's company or the drafters span fewer than three companies.
What the record gives you
The manifest records, for every step, the model, whether it ran through an API or by hand, fingerprints of the prompt and answer, the time, the key to the labels and both verdicts. It even records whether a search tool was really attached to each request. Some courts ask about AI use: the Northern District of Texas requires a brief prepared with generative AI to "disclose this fact on the first page" (LR 7.2(f)). A Docprep run folder holds exactly the material for such a notice. It also saves money: resume runs only the steps that have no file yet, so a failed call never repeats a paid one.
Two ways to run it
By hand, in the chat sites, no API key. The manual formula writes a file MANUAL-<role>.md for each step with the prompt and the model to use. You paste it into a fresh chat, paste the answer back under the marker line and run resume. A full run is seven pastes: four drafts (Claude, ChatGPT, Gemini and Grok), the merge, and two checks. The rules care which company a model comes from, not which plan you pay for, and this path also lets you use the chat sites' deep-research modes.
With API keys, automatically. Set keys for Anthropic, OpenAI and Google, and Docprep calls the models itself, each with its own company's search tool; Grok and a Llama model can join as extra drafters. The example configuration has a basic formula for routine documents and an enhanced one for anything a court will read, built from models available in September 2026; any set from different companies that keeps the rules will do.
The protocol calls itself a ramp: "It was built for someone who cannot take the stairs: who cannot hold five interfaces open at once, read them against each other, and carry the answer back." Docprep does the carrying.
How it differs from an LLM council
Docprep belongs to the family of LLM councils, multi-agent debate and LLM-as-a-judge. Andrej Karpathy's popular llm-council has models rank each other with names hidden, then a "Chairman" model writes one final answer. Docprep differs in four ways, all enforced by code: the drafters never read each other, the merger is not told who wrote what, the closing verdict comes from a different company than the merger, and every step leaves a record. It also stops before any final rewrite: you get the document and the reports, not a text quietly corrected for you.
How to start
You need Python 3 and the code from the GitHub page.
git clone https://github.com/vadimchernets/docprep
cd docprep
python3 -m venv .venv && source .venv/bin/activate
pip install -r requirements.txt
cp config.example.yaml config.yaml
python3 docprep.py run --brief briefs/example_brief.md --formula manual
python3 docprep.py resume --run runs/<id>
With API keys, put the model names your accounts offer into config.yaml, then run python3 docprep.py check and python3 docprep.py run --brief briefs/my-brief.md --formula enhanced. The offline tests (python3 -m pytest tests/test_offline.py, five tests) run the whole pipeline without keys or network.
Where it comes from
Docprep is the reference implementation of the protocol in the paper The Missing Variable in AI-Assisted Litigation: Architecture and the Quality of Pro Se Access to Justice by Vadym Chernets (SSRN 7120940, DOI 10.2139/ssrn.7120940). The paper argues that how AI help is arranged, one model asked once or several models from different companies checking one another, is a variable in the quality of what self-represented litigants file, and it draws on a federal case in which the author was the plaintiff without a lawyer. The code is one Python file under the MIT licence, the protocol text PROTOCOL.md is under CC BY 4.0, and everything is at github.com/vadimchernets/docprep. To put one question to the AI tools on your computer, see After Chat and Sidecall; to ask the AI chat sites through your own browser, see Roundcall.
Vadym Chernets also builds Poly A1, an app in which AIs from different companies check each other's work.